SAN FRANCISCO, Oct 8 — Arena, the company behind one of the most widely followed public leaderboards for artificial intelligence models, has raised $200 million in a Series B round at a valuation of $3.1 billion, nearly doubling its value in the space of a few months.
The round was led by Lightspeed Venture Partners and Khosla Ventures, with participation from Salesforce Ventures, 01 Advisors, Dell Technologies Capital, Endeavor Catalyst, Andreessen Horowitz and Felicis.
The financing follows a $150 million Series A in January that valued Arena at $1.7 billion. Its rapid rise reflects how evaluating AI models — deciding which system is best for a given task — has become one of the most commercially important problems in the industry.
Key facts at a glance
• Round: $200 million Series B
• Valuation: $3.1 billion, up from $1.7 billion at the January Series A ($150 million)
• Leads: Lightspeed Venture Partners and Khosla Ventures
• Other investors: Salesforce Ventures, 01 Advisors, Dell Technologies Capital, Endeavor Catalyst, Andreessen Horowitz, Felicis
• Revenue: annualised revenue from about $30 million in January to about $100 million by June
• Origin: research project at UC Berkeley, 2023
• Products: public leaderboards, AI Evaluations (launched September last year), new alignment leaderboard
From academic project to billion-dollar business
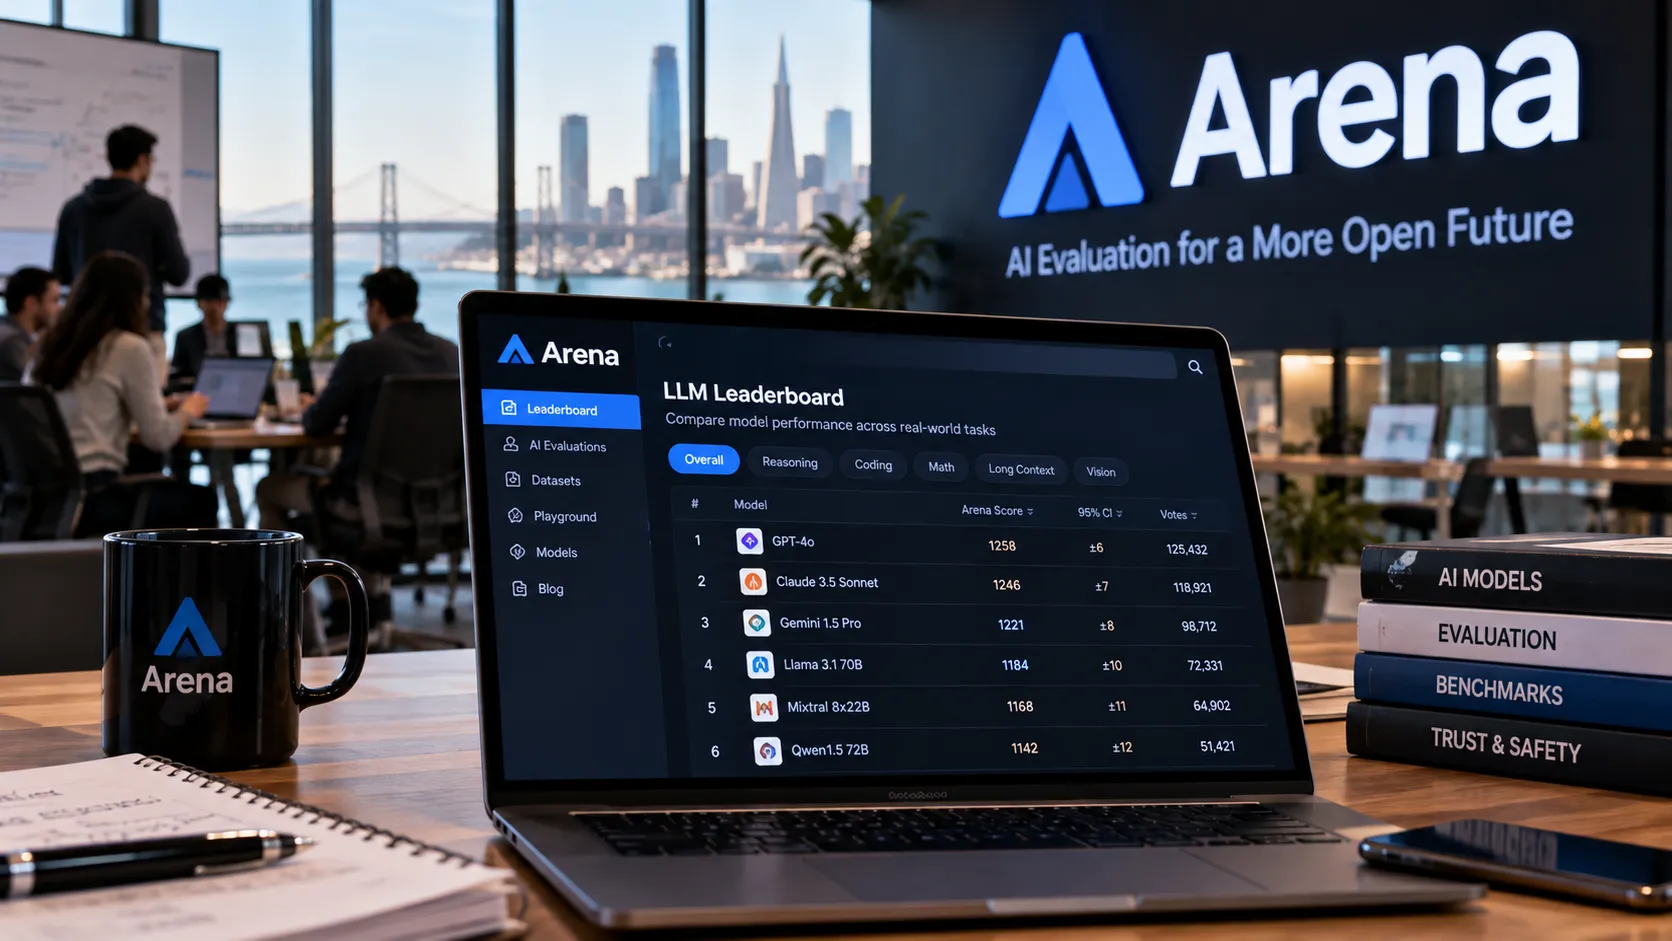
Arena began in 2023 as a research project at the University of California, Berkeley. Its core idea was simple: rather than relying only on fixed benchmark tests, let real users compare the outputs of two anonymous AI models side by side and vote on which response is better. Aggregated across very large numbers of comparisons, those votes produce a ranking that reflects human preferences across a wide range of real-world tasks.
The approach caught on quickly. As new models from OpenAI, Google, Anthropic, Meta and a growing roster of open-source developers were released, their positions on the Arena leaderboard became a closely watched signal of performance. Model makers began citing their rankings in launch announcements, and the leaderboard became a reference point for developers, investors and the media.
Revenue that surprised investors
The commercial traction behind the valuation is striking. Arena's annualised revenue rose from about $30 million in January to about $100 million by June, more than tripling in roughly six months.
The company has built its business around helping enterprises and AI developers evaluate models for their specific needs. In September last year it launched AI Evaluations, a commercial service that allows companies to test models against their own use cases and data. It has also introduced new leaderboards, including one focused on alignment — how well models follow instructions and behave in line with intended values and safety requirements.
Why evaluation matters now
The explosion in the number of capable AI models has created a new problem for businesses: choice. A company building a customer service chatbot, a coding assistant or a document-analysis tool can now choose from dozens of models with different strengths, costs, speeds and risk profiles. Selecting the wrong one can mean higher costs, poorer performance or reputational damage.
Traditional benchmarks — standardised tests that measure performance on specific tasks — have become less reliable as models are optimised to score well on them. Evaluation based on human preferences and real-world tasks offers a complementary view. Enterprises increasingly want independent, ongoing assessments rather than relying solely on claims made by model developers.
That shift has created a market for evaluation platforms, and Arena's growth suggests it has captured a leading position. Its investors are betting that evaluation will become a permanent layer in the AI stack, much as testing, monitoring and security became essential layers in software development.
Questions of neutrality
Arena's influence also brings scrutiny. Because model developers have strong incentives to rank highly on its leaderboard, critics in the AI research community have raised questions about how rankings are produced and whether large labs gain advantages through testing many private model variants before release. Maintaining trust in the neutrality of its rankings is essential to Arena's value, particularly as it earns revenue from companies whose models it evaluates.
The company has responded by publishing details of its methodology and expanding the range of leaderboards and evaluation categories. How it balances commercial growth with independence will be central to its long-term credibility.
The size of the round also reflects investor conviction that evaluation spending will grow alongside model spending. As enterprises allocate larger budgets to AI deployments, a growing share is expected to go towards testing, monitoring and assurance — the work of proving that systems are accurate, safe and worth their cost before they reach customers.
How the business makes money
Arena's public leaderboard is free to use and serves as its most visible product, attracting a large community of users who generate the comparisons that underpin its rankings. The commercial business sits alongside it. Model developers pay for structured evaluations of their systems before and after release, and enterprises pay to test how different models perform on their own tasks and data. That combination — a free public product that builds trust and data, and paid services that apply the same methodology to private use cases — is a familiar model in technology, but rarely has it scaled this quickly in evaluation.
What it means for founders and investors
For the global start-up ecosystem, Arena's trajectory is a reminder that some of the most valuable opportunities in AI lie not in building models but in the infrastructure around them. Tools for evaluation, monitoring, security and orchestration are attracting significant investment as enterprises move from experimentation to deployment.
For Indian founders and engineers — many of whom are building AI applications for global customers — independent evaluation platforms are increasingly part of the toolkit for choosing models and demonstrating performance to clients. And for the diaspora of Indian-origin researchers in AI labs and universities, Arena's rise from a Berkeley research project shows how academic work can become a global business at remarkable speed.
With $200 million in new funding, Arena is expected to expand its evaluation products, deepen its enterprise offering and broaden its leaderboards. In an industry where new models arrive almost weekly, the company that helps users decide which ones to trust is building a valuable position.